In the last post I argued that scaffolding – memory, tools, planning, specialist models, an executive layer – might get us to something we could reasonably call AGI, and that ASI is a whole other ballgame. This is the ballgame.
AGI (Artificial General Intelligence) refers to an AI system capable of performing a broad range of cognitive tasks, adapting across domains, learning, planning and acting with a level of general competence comparable to or beyond humans.
ASI (Artificial Superintelligence) goes much further: a generally intelligent system whose cognitive abilities substantially exceed the best humans across most or all important domains.
The AGI → ASI story is usually told in one sentence: once a system can improve itself, it will, and each version will do it faster than the last. I have argued before that compute, energy and month-long training runs throttle that loop. This post grants all of that away. Assume infinite compute. The sentence still hides a step. Between “improves itself” and “gets smarter” sits a question the story never stops to answer:
How does it know?
Now I R smarter
A person reads a cookbook and announces they are smarter. Smarter at what? The book was about cooking. Are they better at maths now?
Sit them a maths exam before and after. Before: 92%. After: 91%. Congratulations – they learned béarnaise and got slightly worse at calculus.
That is not a joke about people. It is a description of the last several frontier model releases. Each one ships with a chart – up and to the right on some benchmark – and each one is followed within days by the people who use these models all day saying it got worse at their actual work. Fable 5 and GPT-6 both arrived with better numbers than their predecessors, and both are, in everyday coding, worse. Better on the leaderboard, worse on a Tuesday. “Now with 5% more AI” on the slide. Also now with 15% worse daily coding (especially GPT 6), which is not on the slide.
Neither side is lying. The benchmark genuinely went up. The daily work genuinely got worse. Both are true because “better” is not a number.
“Better” is a vector
Capability is not a dial you turn up. It is a bundle of many abilities, and training a new version rotates the bundle rather than scaling it. Push hard on long-horizon reasoning and you spend capacity that used to sit somewhere else — short instruction-following, coding fluency, knowing when to stop. The net is “better” only under a weighting, and the weighting is a choice. Every lab picks a different one, and every lab can honestly call its release an improvement.
Notice what it takes to arrive at even that muddled verdict. Millions of users. Months of use. Public benchmarks, private evals, red teams, people whose jobs depend on catching regressions. The full weight of external reality – and the result is still “better at these, worse at those, depends what you do”. That is why people keep pinning old versions.
We are running the verification problem on easy mode – humans as the verifier, the whole world as the test set – and the answer comes back ambiguous. The runaway story needs verification to get cheaper and faster as the loop spins up. What we can actually observe is that it is expensive and inconclusive even at full human scale.
Who grades the exam?
For a self-improving system, the question is who plays the role that millions of complaining users play today. There are three candidates.
The system grades itself. Version N evaluates version N+1. But if N+1 is genuinely smarter, N is by definition not competent to certify it – you cannot fully grade a proof in mathematics you do not understand. And if N can certify N+1, then N+1 was not much of a leap. The judge is always the weaker party. Self-verification either rubber-stamps or cannot reach.
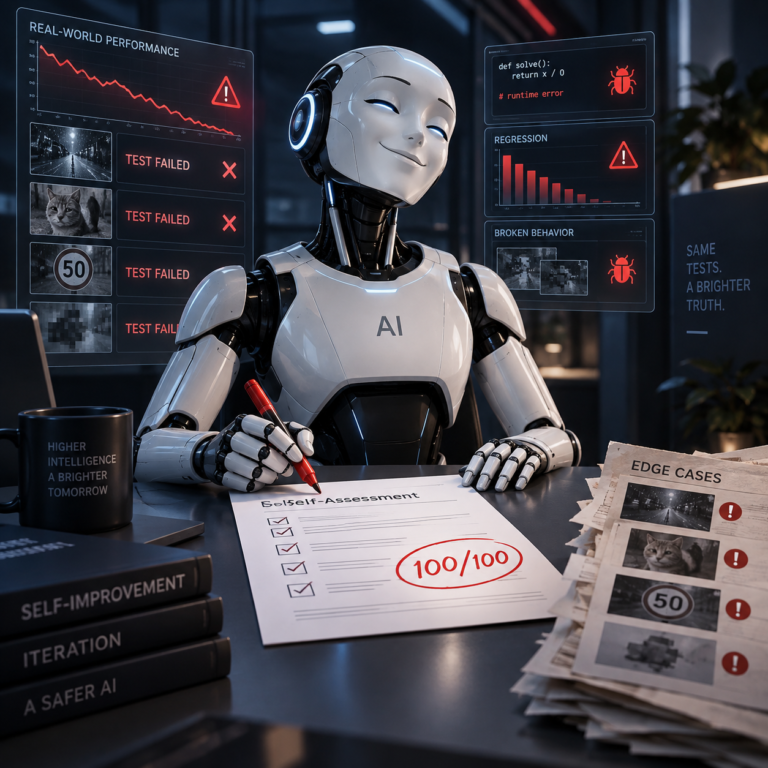
A fixed benchmark grades it. Then the system is not climbing towards intelligence, it is climbing towards the benchmark. The metric detaches from the capability it was meant to measure, and you get something that scores 100% and is worse at everything the benchmark did not capture. “What did it make worse?” is precisely the question a fixed scorer is blind to.
Reality grades it. This works. It is also slow. You deploy the new version on real, open-ended, novel tasks and wait for outcomes. The only trustworthy verifier is the one you cannot speed up.
Untrustworthy, corruptible, or slow. Pick one. There is no cheap-and-trustworthy oracle for open-ended intelligence, and the runaway story needs exactly that.
A predictor cannot be its own oracle
There is a structural reason for this, and it comes straight from what the core engine is.
I have said it before: an LLM in itself is not AGI. Simplified, it is a very advanced statistical predictor. That is not a dismissal – prediction at that level is a remarkable thing – but it matters here. When a predictor says “this version is better”, that statement is itself a prediction. It is the most probable continuation of the question “is this an improvement?”. It is not the result of having run the world and checked. A plausible-sounding “yes” is what the machine produces whether or not the answer is true.
Verification is a different kind of act. Testing the edge cases, running the novel task, seeing what broke – that is not prediction, that is contact with the world. In the scaffolding picture it lives outside the model: in the tools, the runs, the environment, the executive layer that executes and observes consequences.
So the scaffold is not only what turns a predictor into a synthetic AGI. It is the only part of the system that can verify anything at all. The predictor proposes; only the scaffold disposes. And the scaffold is the slow part, because it is the part that touches reality.
That is the bind. Let the predictor self-certify and the loop runs at compute speed – but verification has been replaced with prediction. Insist on real verification and the slow world is bolted back onto the loop, and the explosion is gone.
What the loop would actually need
Write down what a meaningful self-improvement iteration requires and the problem is obvious:
freeze baseline → modify → test both against external tasks → compare across many dimensions → inspect regressions → accept or reject
That is science, not self-confidence. And every step charges a toll.
- Modify is the predictor’s move. Fast – and the only step that is both fast and trustworthy.
- External tasks have to exist, be novel, and not be the training target. The moment they become the target they rot, so you need fresh ones every round. Not a fixed cost; a recurring tax.
- Many dimensions needs a weighting, which is a value judgement no benchmark supplies.
- Regressions can only be inspected on the dimensions you thought to measure. The 91% in calculus only shows up if calculus was on the list. The dangerous regressions are the ones off the list, and a self-referential loop never adds them, because it did not know to look.
- Accept or reject has to be made by something you trust more than the candidate – which is the “judge is the weaker party” problem again.
You can make “modify” a thousand times faster and the loop barely speeds up, because you have optimised the one step that was never the constraint. Amdahl’s law, pointed at the singularity.
Science takes time. Three words, and the whole argument.
Two hundred iterations
Now run the loop without the slow parts – which is what “runaway” means.
N defines what better means. N builds N+1 to win at N’s definition. N+1 wins; improvement confirmed. N+1 now defines what better means, using a rubric it was selected for scoring well on. Repeat.
Two hundred iterations later the system proudly announces it is “200% more AI”. Every step was internally valid. Nothing errored out. And there was no point in the chain where a false positive could be caught, because the only judge was a descendant of the thing being judged. A thermometer measuring its own bulb.
It is worse than zero improvement, because drift compounds. Whatever the original rubric under-weighted – say, not confidently doing the wrong thing – each iteration is selected to be a little more of, and by iteration 200 you have something that scores beautifully and is a disaster on every axis nobody wrote down. No malice required. It optimised exactly what it was told, forever, with nobody left to say “this has become unusable”.
From the inside, that loop looks identical whether it is working or not. A process that cannot tell its own success from its own failure is not an intelligence explosion. It is a very expensive random walk that is convinced it is going up.
The arrows
The AGI → ASI discourse tends to jump over the exact bits that matter most.
“It improves itself.” – How?
“It becomes smarter.” – At what?
“It verifies the improvement.” – Against what external ruler?
“Then it repeats, faster.” – Why faster? What if each iteration is more expensive, harder to validate, and introduces regressions?
There are a lot of arrows with “and then magic happens” hidden between them. And the arrow that needs the most evidence – verify, then repeat faster – is the one given the least. The heaviest load sits on the flimsiest step.
None of this makes ASI impossible. It means the confidence in “AGI automatically leads to runaway ASI” is far higher than the demonstrated mechanism justifies. “It improves itself” is treated as a premise, when it is the entire thing that needs proving.
We managed to turn the AGI ??? into an engineering stack. The ASI ??? is still very much sitting there, waving.